My local models are worse than Claude at almost everything, but they still run most of my workflow for $0
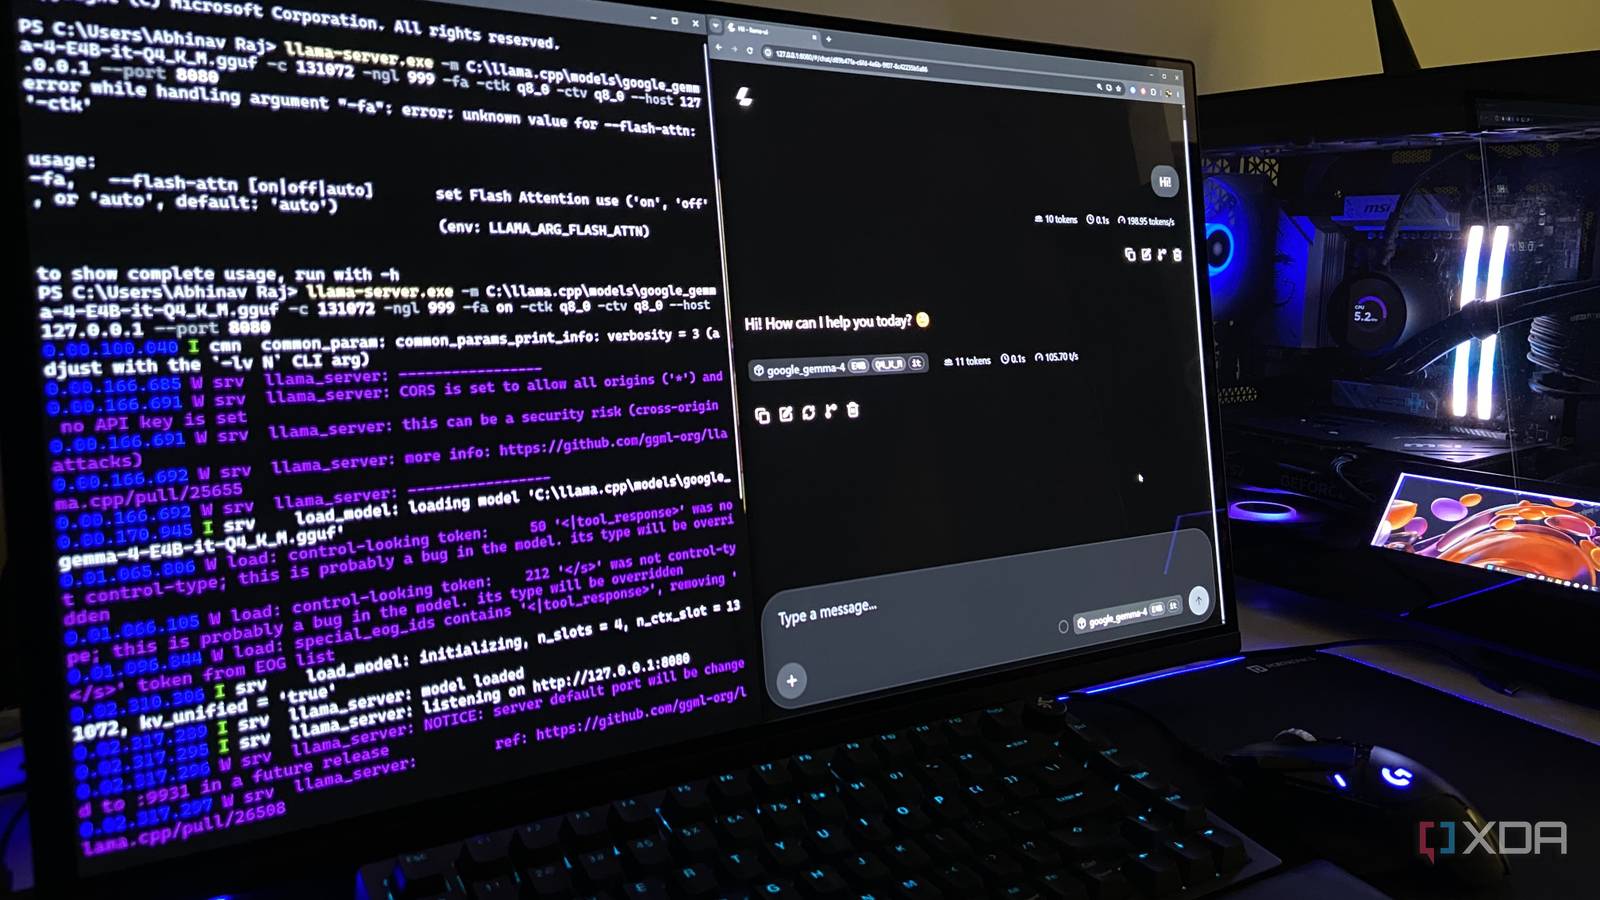
Photo: XDA Developers
It's not lost on me that any one of Anthropic's models can outperform the models I run on my 16GB Nvidia GPU. I'd wager even Sonnet 5.5 can write much better code, keep track of conversations that just go on and on, and catch mistakes that both my Qwen3.6 and Gemma 4 would walk right past. If you put them side by side on any benchmark, Claude will take the win in literally any workflow, and it won't be close. And yet, when I look back on a typical week, my local AI stack running on my RTX 4070 Ti Super gets more prompts from me than Claude ever does.
First reported by XDA Developers. This page is a short excerpt; the full text is theirs.
Read the full story at XDA Developers